

When maintaining a WordPress multilingual site (especially using the Polylang plugin), tag proliferation is a headache for countless webmasters. Over time, due to varying user input habits or limitations in the system’s synchronization mechanism, websites tend to accumulate a massive number of synonymous tags.
The most typical cases are mixed Chinese and English (such as “支付宝” and “alipay”) and minor differences (such as “Redis缓存” and “Redis 缓存”, differing by just a single space). These duplicate tags not only make backend management chaotic but also scatter content, severely diluting SEO weight.
Recently, I thoroughly cleaned up the site’s tag library, achieving an “atomic-level” safe merge of Chinese and English tags in a Polylang environment. This article will share the entire process of this practical operation.
1. The Pain Point: Tag Redundancy and Multilingual Traps
Before the cleanup, the site’s tag ecosystem faced several severe issues:
- Synonymous tags fragmenting content: Taking payment-related articles as an example, some articles were tagged with “支付宝” and others with “alipay”. When readers clicked the tag, they could only see a portion of the articles, resulting in a terrible experience.
- Chinese-English mapping disconnection: Although Polylang can associate Chinese and English tags, in actual operation, due to caching or synchronization script flaws, the translation relationships of many Chinese and English tags are disconnected at the underlying level, making it impossible to find the corresponding language via official functions at all.
- Space and case traps: “Redis缓存” and “Redis 缓存” look the same to the naked eye, but they are two independent Terms in the database. A direct merge is highly prone to omissions.
2. Practical Results: From Chaos to Unification
To completely solve this problem, I wrote a merge script featuring “penetrative lookup” and “atomic validation”. Here is a direct comparison before and after the cleanup:
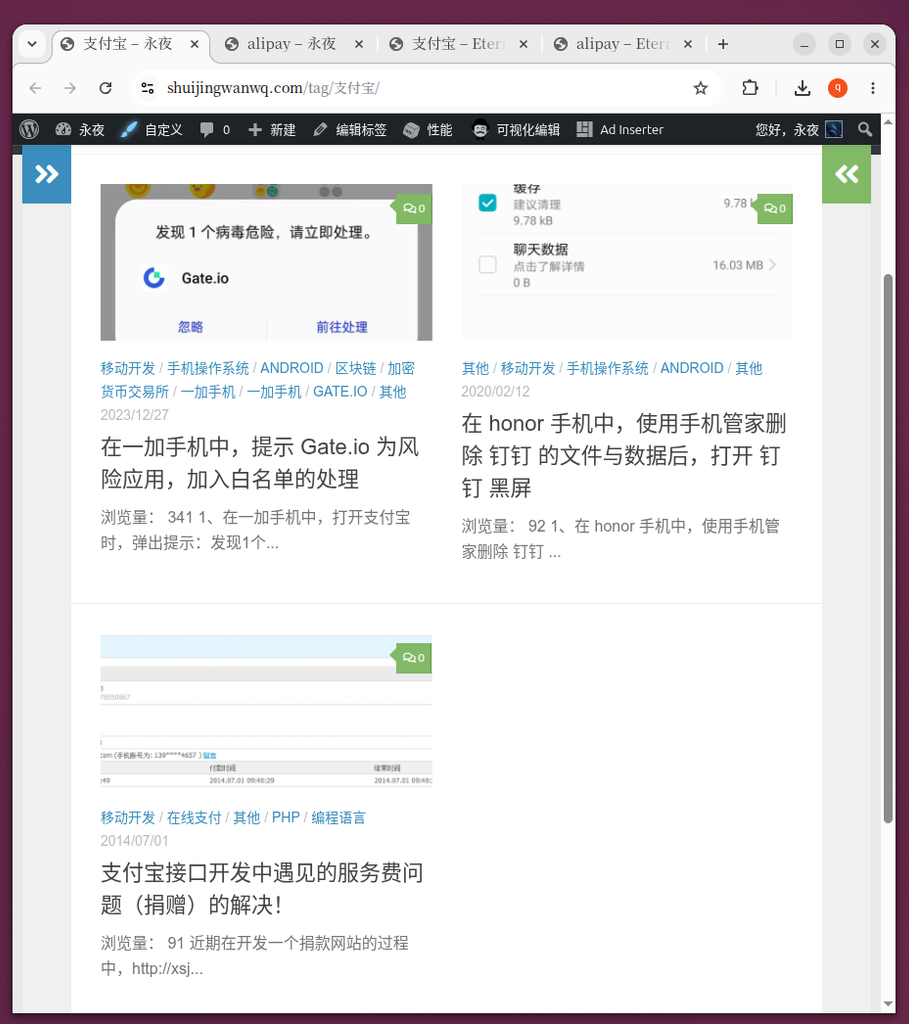
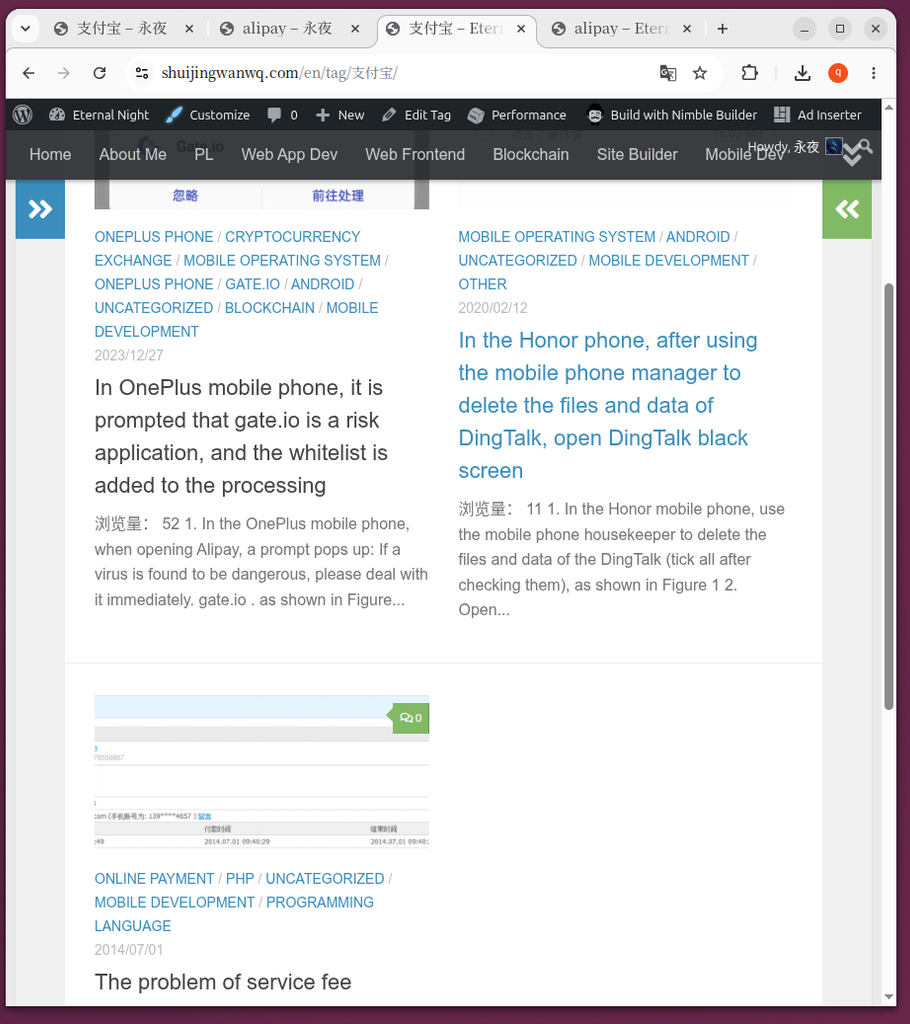
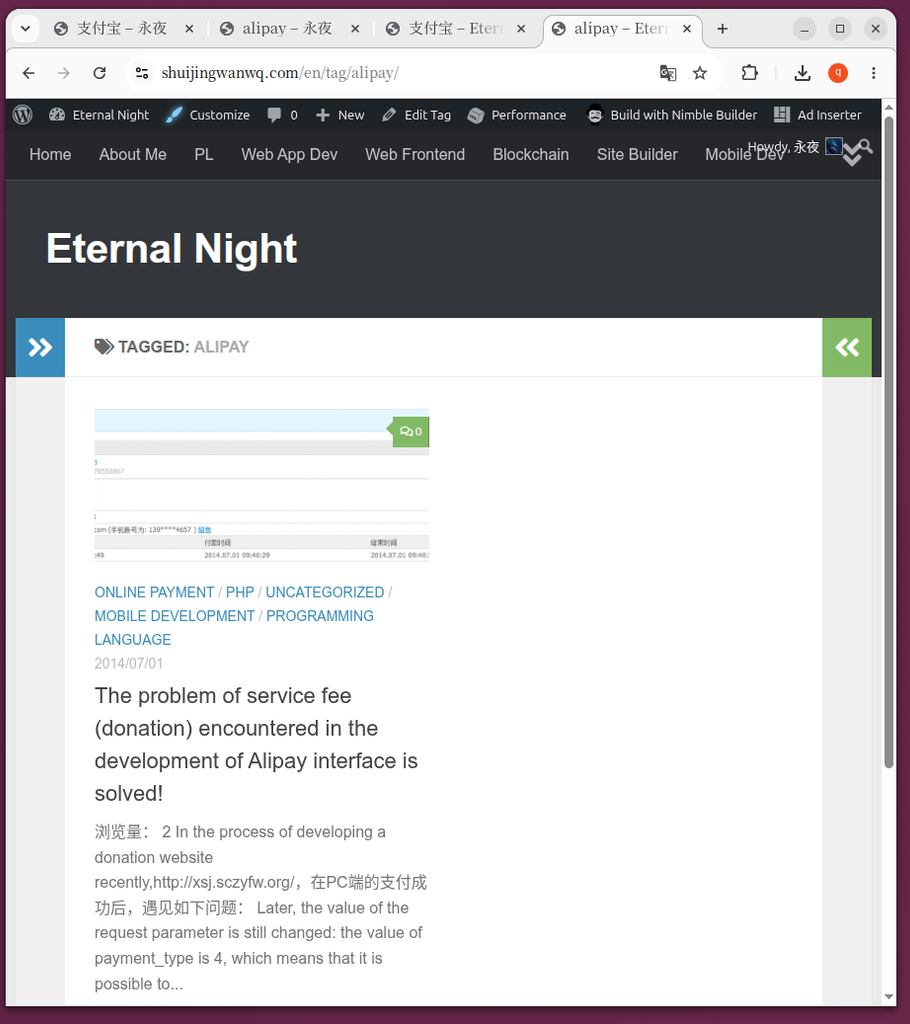
📸 Before Cleanup: Fragmented Tag Pages (Figures 2, 3, 4, 5)
Before the script ran, the site suffered from severe synonymous tag fragmentation:
- Figure 2 & Figure 3: In the Chinese environment, accessing
/tag/支付宝/and/tag/alipay/led to two independent pages, with articles scattered across both. - Figure 4 & Figure 5: In the English environment, the same fragmentation issue existed with
/en/tag/支付宝/and/en/tag/alipay/.
/tag/支付宝/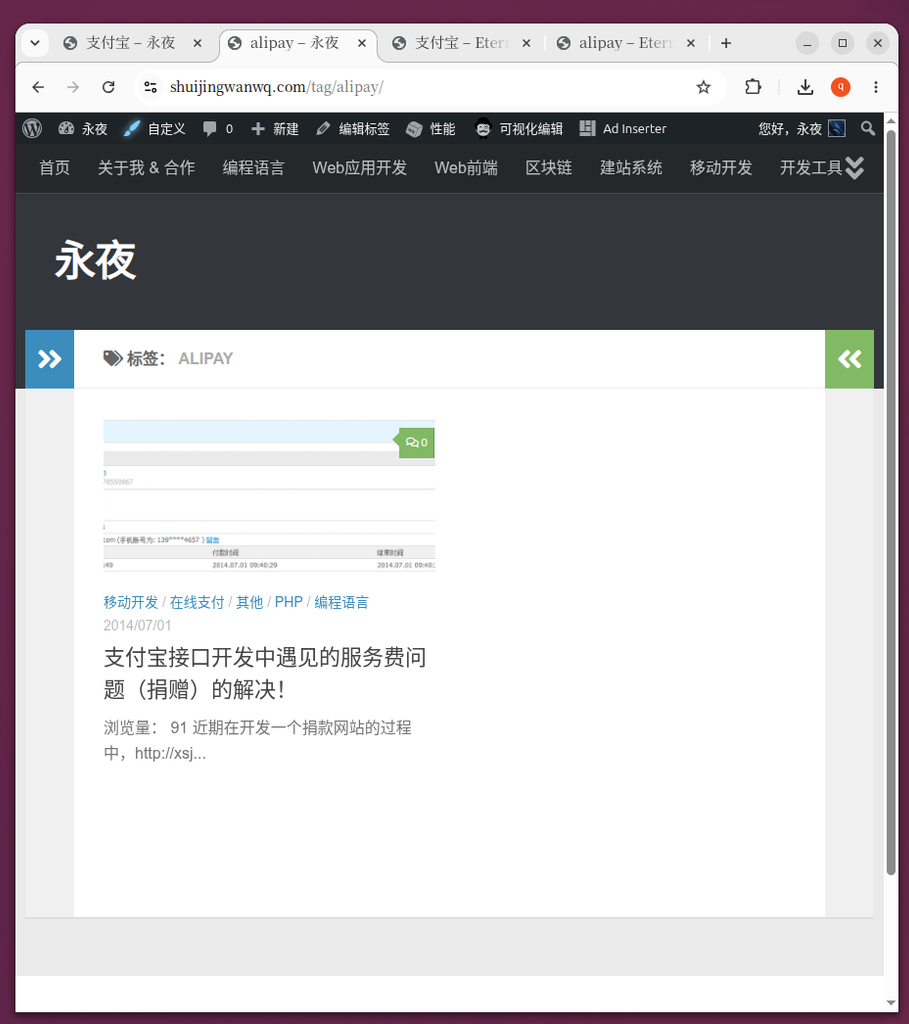
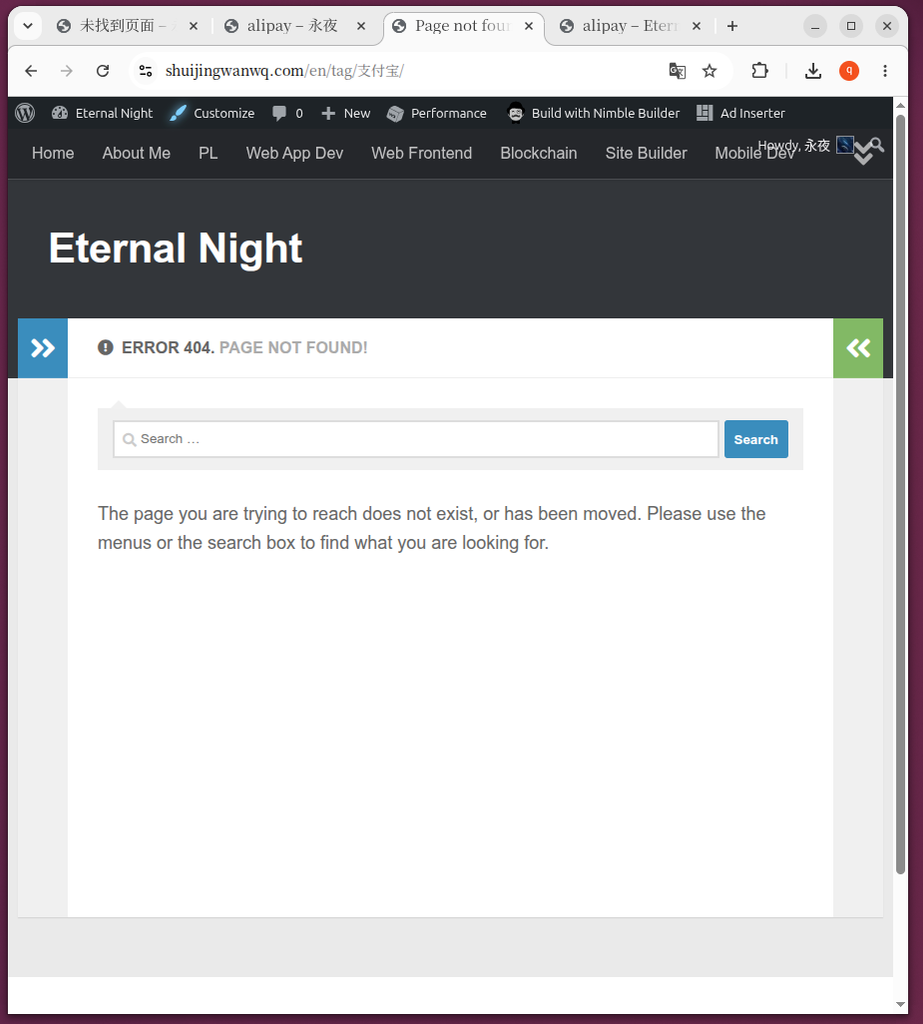
📸 After Cleanup: Unification and the Inevitability of 404s (Figures 6, 7, 8, 9, 10)
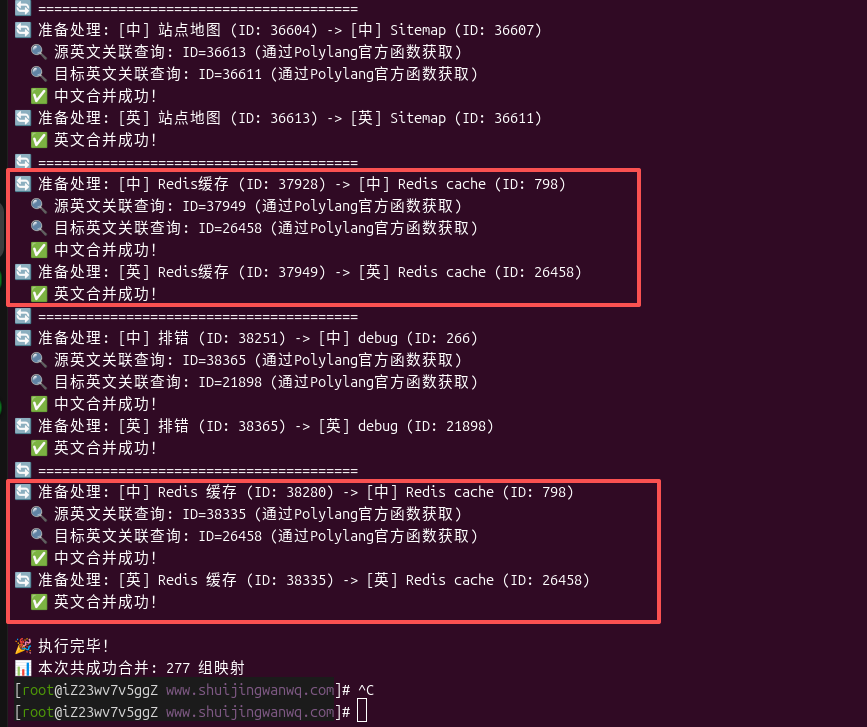
After the script executed (as shown in the terminal log in Figure 6), the system began merging Chinese and English tags in pairs.
Indications of a successful merge (Figure 8, Figure 10):
- Figure 8: Accessing
/tag/alipay/, the articles originally belonging to the “支付宝” tag have been perfectly transferred over, merging into one. - Figure 10: The English version
/en/tag/alipay/similarly gathered all related articles.
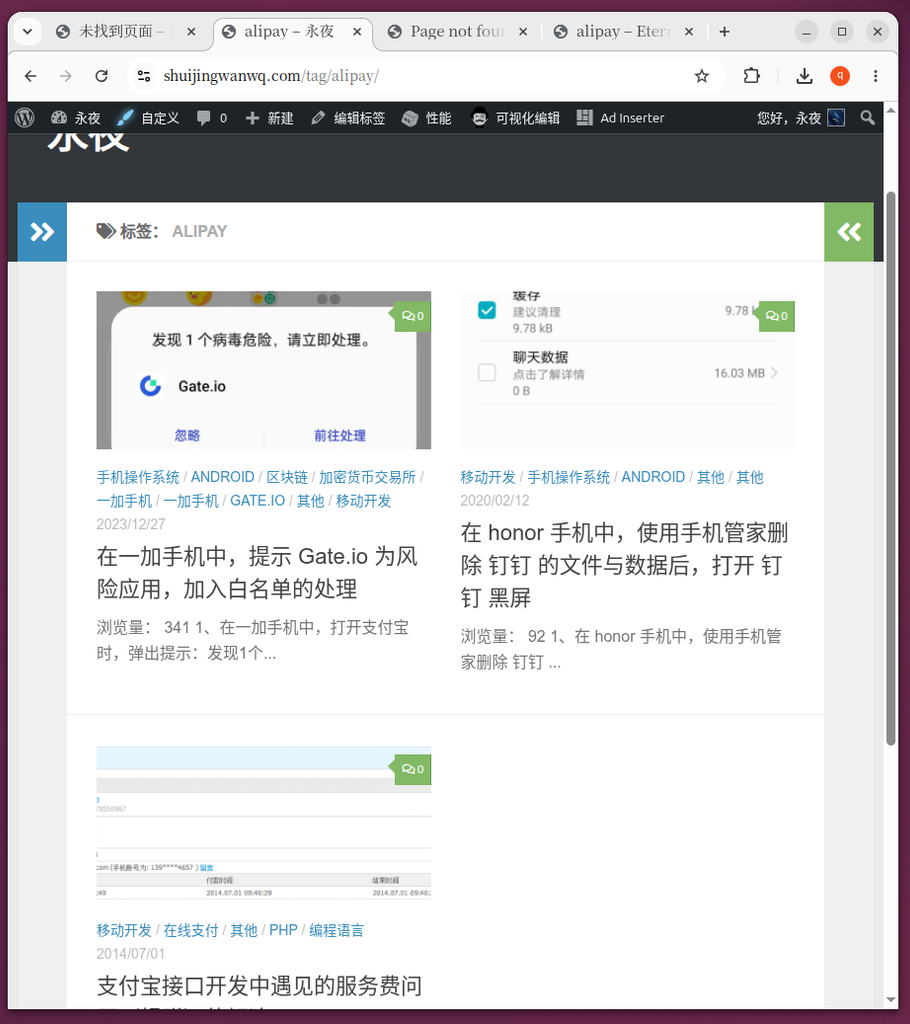
/tag/alipay/, the articles originally belonging to the “支付宝” tag have been perfectly transferred over, merging into one.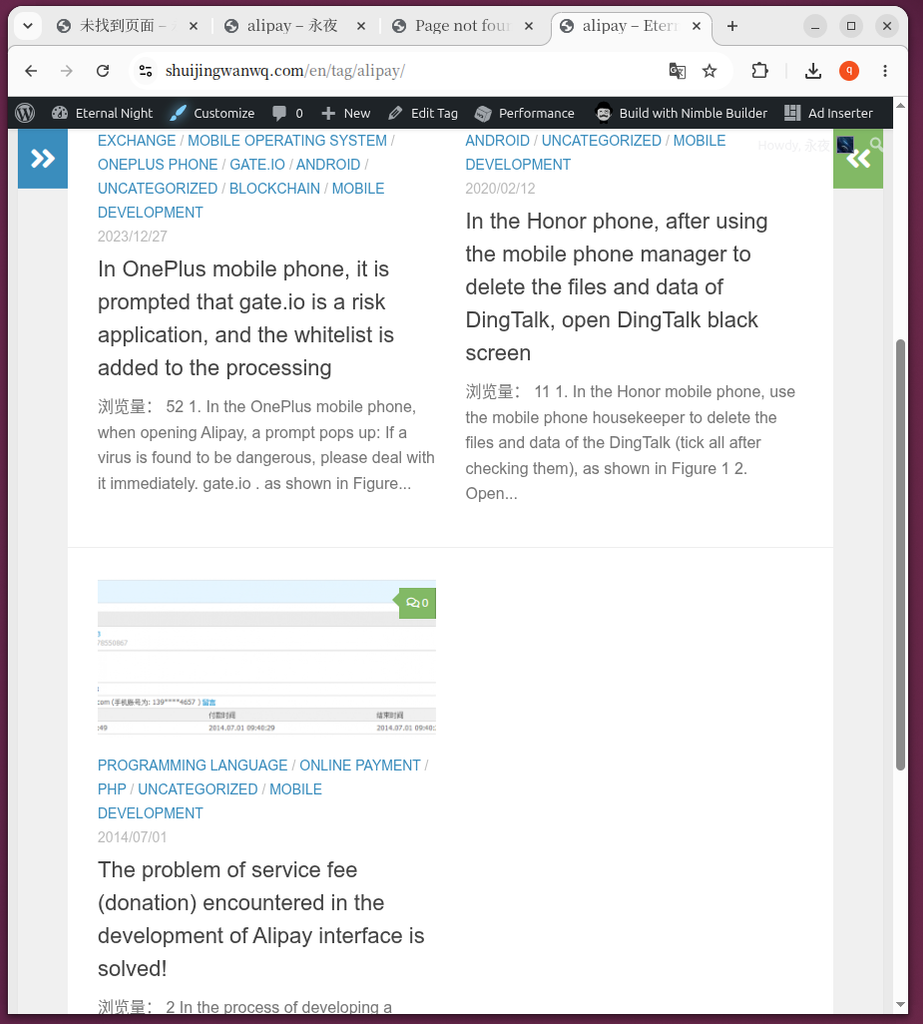
/en/tag/alipay/ similarly gathered all related articles.Indications of old tag invalidation (Figure 7, Figure 9):
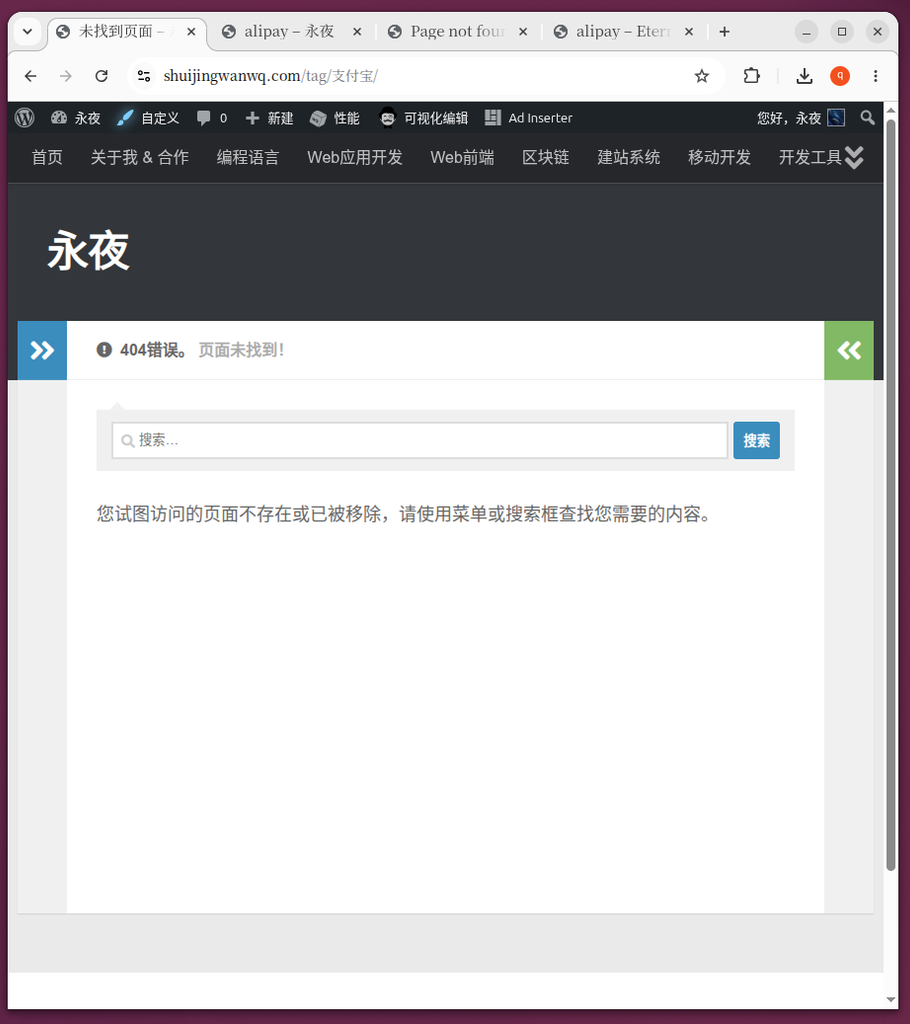
- Figure 7 & Figure 9: When you access the old source tag URL again (such as
/tag/支付宝/or/en/tag/支付宝/), a 404 error occurs. This is a normal and expected phenomenon after merging. Because WordPress’swp_delete_termfunction does not automatically create 301 redirects for old tags when merging. The old tags have been deleted as entities, so their URLs naturally become invalid.
3. Core Breakthrough: Solving the Synonym Problem of “Redis缓存” and “Redis 缓存”
As highlighted in the terminal log (Figure 6):
Preparing to process: [zh] Redis缓存 (ID: 37928) -> [zh] Redis cache (ID: 798)
Preparing to process: [en] Redis缓存 (ID: 37949) -> [en] Redis cache (ID: 26458)

Preparing to process: [zh] Redis 缓存 (ID: 38280) -> [zh] Redis cache (ID: 798)
Preparing to process: [en] Redis 缓存 (ID: 38335) -> [en] Redis cache (ID: 26458)The two obsessive-compulsive-inducing tags “Redis缓存” (without a space) and “Redis 缓存” (with a space) were ultimately both accurately merged under the unified “Redis cache”.
This is because, before merging, the script does not rely on tag names for matching, but instead precisely specifies the target ID via a CSV mapping table. As long as they are identified as synonyms via an API or algorithm and a mapping table is generated beforehand, they can all be captured regardless of a difference of a single space or letter.
4. Technical Reveal: How to Achieve a “Zero-Error” Atomic Merge?
Manipulating the Polylang database in a CLI environment is like walking a tightrope; a single misstep can lead to Chinese-English desynchronization. The core reason this script can be safely deployed lies in the following three mechanisms:
- Penetrative English tag lookup:
In the command line, Polylang’s cache is often missing, and the official functionpll_get_term()frequently returns empty. The script employs a four-layer defensive lookup: official function -> direct Term Meta query -> reverse Meta search -> query database by slug + language. Because the synchronization script copies the Chinese slug to English as-is, this final “lookup by slug” layer acts as the most solid fallback, ensuring that no matter how broken the translation relationship is, the real English tag ID can always be unearthed. - Absolute “query before delete” principle:
The script never queries while deleting. If you query its slug to find the English tag after deleting the Chinese source tag, it will certainly not be found (because the slug is deleted along with the tag). The script queries and locks all source and target IDs for both Chinese and English into variables before executing any deletion operations. - Strict atomic validation (all or nothing):
If the source tag has an English version, but the target tag’s English version is missing (and is not auto-created to prevent data pollution), the script directly flags it as an anomaly and skips the entire row, not even merging the Chinese. This prevents the generation of dirty data where “the Chinese merged, but the English didn’t”.
5. Appendix: Core Code and Data Format
To allow friends encountering the same issue to directly reuse it, here are the data format specifications and the complete PHP script code from this operation.
1. CSV Mapping Table Format (tag_mapping_result.csv)
The script relies on a pre-prepared CSV file to determine the merge strategy. The file must be placed in the output/ folder in the same directory as the script, formatted as follows:
	Source Tag ID,Source Tag Name,Target Tag ID,Target Tag Name,Status
	148,支付宝,158,alipay,API match successful
	37928,Redis缓存,798,Redis cache,API match successful
38280,Redis 缓存,798,Redis cache,API match successful- First four columns: Clearly specify the IDs and names of the source and target tags (the names are only used for console log display and do not participate in logic matching, perfectly resolving minor difference issues like spaces).
- Fifth column (Status): The script only processes rows with a status of
API匹配成功; rows with other statuses are safely ignored.
2. PHP Merge Script (merge-tags.php)
Save the following code as merge-tags.php and place it in the WordPress root directory to run.
<?php
if (php_sapi_name() !== 'cli') {
die("❌ 请在命令行运行\n");
}
require __DIR__ . '/wp-config.php';
global $wpdb, $polylang;
$csv_file = __DIR__ . '/output/tag_mapping_result.csv';
if (!file_exists($csv_file)) {
die("❌ CSV文件不存在: {$csv_file}\n");
}
// 解析命令行参数
$test_ids = [];
$is_all = false;
$dry_run = in_array('--dry-run', $argv);
if ($dry_run) {
echo "🏃♂️ 【模拟执行模式】:仅输出将要执行的操作,不会修改数据库!\n\n";
}
$argv = array_diff($argv, ['--dry-run']);
if (isset($argv[1])) {
if ($argv[1] === '--all') {
$is_all = true;
echo "🚀 批量模式:处理 CSV 中所有 API匹配成功 的映射\n\n";
} else {
$test_ids = array_slice($argv, 1);
$test_ids = array_map('intval', $test_ids);
$test_ids = array_filter($test_ids);
if (empty($test_ids)) {
die("❌ 无效的ID参数。用法: php merge-tags.php 7 27 [--dry-run] 或 php merge-tags.php --all [--dry-run]\n");
}
echo "🧪 测试模式:仅处理源标签 ID 为 [" . implode(', ', $test_ids) . "] 的映射\n\n";
}
} else {
die("ℹ️ 请指定要测试的源标签ID,或使用 --all。\n用法: php merge-tags.php 7 27 [--dry-run]\n用法: php merge-tags.php --all [--dry-run]\n");
}
$target_lang = 'en';
$processed = 0;
/**
* 穿透式获取英文翻译ID函数
*/
function get_en_term_id_safe($zh_term_id, $target_lang) {
global $wpdb;
$en_id = pll_get_term($zh_term_id, $target_lang);
if ($en_id) return ['id' => $en_id, 'method' => 'Polylang官方函数'];
$translations = $wpdb->get_var($wpdb->prepare(
"SELECT meta_value FROM $wpdb->termmeta WHERE term_id = %d AND meta_key = '_pll_translations_post_tag'",
$zh_term_id
));
if ($translations) {
$trans = maybe_unserialize($translations);
if (!empty($trans[$target_lang])) return ['id' => $trans[$target_lang], 'method' => '当前Term的Meta直接提取'];
}
$search_string = sprintf('i:%d;', $zh_term_id);
$meta_values = $wpdb->get_col($wpdb->prepare(
"SELECT meta_value FROM $wpdb->termmeta WHERE meta_key = '_pll_translations_post_tag' AND meta_value LIKE %s",
'%' . $wpdb->esc_like($search_string) . '%'
));
if (!empty($meta_values)) {
foreach ($meta_values as $meta_value) {
$trans = maybe_unserialize($meta_value);
if (!empty($trans[$target_lang])) return ['id' => $trans[$target_lang], 'method' => '逆向Meta查找'];
}
}
$zh_term = get_term($zh_term_id, 'post_tag');
if ($zh_term && !is_wp_error($zh_term)) {
$en_terms = get_terms([
'taxonomy' => 'post_tag',
'slug' => $zh_term->slug,
'lang' => $target_lang,
'hide_empty' => false,
]);
if (!is_wp_error($en_terms) && !empty($en_terms)) return ['id' => $en_terms[0]->term_id, 'method' => '按别名+语言查找'];
}
return ['id' => 0, 'method' => '未找到'];
}
if (($handle = fopen($csv_file, 'r')) !== FALSE) {
fgetcsv($handle); // 跳过表头
while (($data = fgetcsv($handle)) !== FALSE) {
if (count($data) < 5) continue;
$source_zh_id = intval($data[0]);
$source_zh_name = trim($data[1]);
$target_zh_id = intval($data[2]);
$target_zh_name = trim($data[3]);
$status = trim($data[4]);
if ($status !== 'API匹配成功' || empty($target_zh_id)) continue;
if (!$is_all && !in_array($source_zh_id, $test_ids)) continue;
echo "🔄 ========================================\n";
echo "🔄 准备处理: [中] {$source_zh_name} (ID: {$source_zh_id}) -> [中] {$target_zh_name} (ID: {$target_zh_id})\n";
// ==============================================================================
// 核心逻辑:严格校验,绝不自动创建
// ==============================================================================
$source_en_info = get_en_term_id_safe($source_zh_id, $target_lang);
$target_en_info = get_en_term_id_safe($target_zh_id, $target_lang);
$source_en_id = $source_en_info['id'];
$target_en_id = $target_en_info['id'];
echo " 🔍 源英文关联查询: ID=" . ($source_en_id ?: '无') . " (通过" . $source_en_info['method'] . "获取)\n";
echo " 🔍 目标英文关联查询: ID=" . ($target_en_id ?: '无') . " (通过" . $target_en_info['method'] . "获取)\n";
$can_merge_en = false;
if ($source_en_id) {
// 源标签有英文版,目标英文也必须已存在
if ($target_en_id) {
$can_merge_en = true;
} else {
echo " ❌ 致命错误:源标签有英文(ID:{$source_en_id}),但目标标签无英文!为保证数据一致,跳过本次中英文合并!\n";
continue; // 直接中止整行操作,中文也不合并
}
} else {
echo " ℹ️ 源标签无英文翻译,仅合并中文即可\n";
}
// ==============================================================================
// 执行阶段:条件已全部满足,开始合并
// ==============================================================================
$zh_success = false;
// 1. 合并中文
if ($dry_run) {
echo " [模拟] 将删除中文源标签 {$source_zh_id},并将文章转移至 {$target_zh_id}\n";
$zh_success = true;
} else {
$result_zh = wp_delete_term($source_zh_id, 'post_tag', ['default' => $target_zh_id, 'force_default' => true]);
if (is_wp_error($result_zh)) {
echo " ❌ 中文合并失败: " . $result_zh->get_error_message() . " (英文也不再执行合并)\n";
continue;
}
echo " ✅ 中文合并成功!\n";
$zh_success = true;
}
// 2. 合并英文 (只有当中文成功,且校验允许合并英文时才执行)
if ($zh_success && $can_merge_en) {
echo "🔄 准备处理: [英] {$source_zh_name} (ID: {$source_en_id}) -> [英] {$target_zh_name} (ID: {$target_en_id})\n";
if ($dry_run) {
echo " [模拟] 将删除英文源标签 {$source_en_id},并将文章转移至 {$target_en_id}\n";
} else {
$result_en = wp_delete_term($source_en_id, 'post_tag', ['default' => $target_en_id, 'force_default' => true]);
if (is_wp_error($result_en)) {
echo " ❌ 英文合并失败: " . $result_en->get_error_message() . "\n";
} else {
echo " ✅ 英文合并成功!\n";
}
}
}
$processed++;
}
fclose($handle);
}
echo "\n🎉 执行完毕!\n";
echo "📊 本次共" . ($dry_run ? '模拟' : '') . "成功合并: {$processed} 组映射\n";
if ($dry_run) {
echo "💡 提示:去掉 --dry-run 参数后才会真正写入数据库。\n";
}3. Execution Method
- Safe simulation (highly recommended for the first run):
php merge-tags.php 148 --dry-run - Single execution:
php merge-tags.php 148 - Full execution:
php merge-tags.php --all
6. SEO Remediation Suggestions
As shown in Figures 7 and 9 above, old tag URLs will 404 after merging. If you have strict SEO requirements, it is recommended to use plugins like Redirection to batch 301 redirect high-weight old tag URLs to the new unified tag URLs after performing a full merge, in order to transfer the link equity.
Conclusion
Through this thorough cleanup, the site has not only bid farewell to trivial synonymous tags like “Redis缓存” and “Redis 缓存”, but also resolved the persistent issue of unstable Polylang multilingual associations. The logical rigor of the code ensures data security, making large-scale tag cleaning no longer a nightmare.